Most of what an AI automation does all day is not clever. It reads an email and decides which team it belongs to. It looks at a document and decides whether it is an invoice. It looks at the next thing an agent wants to do and decides whether that is allowed. For the last two years the answer to every one of those small questions has been a call to a large language model, because that was the tool we had.
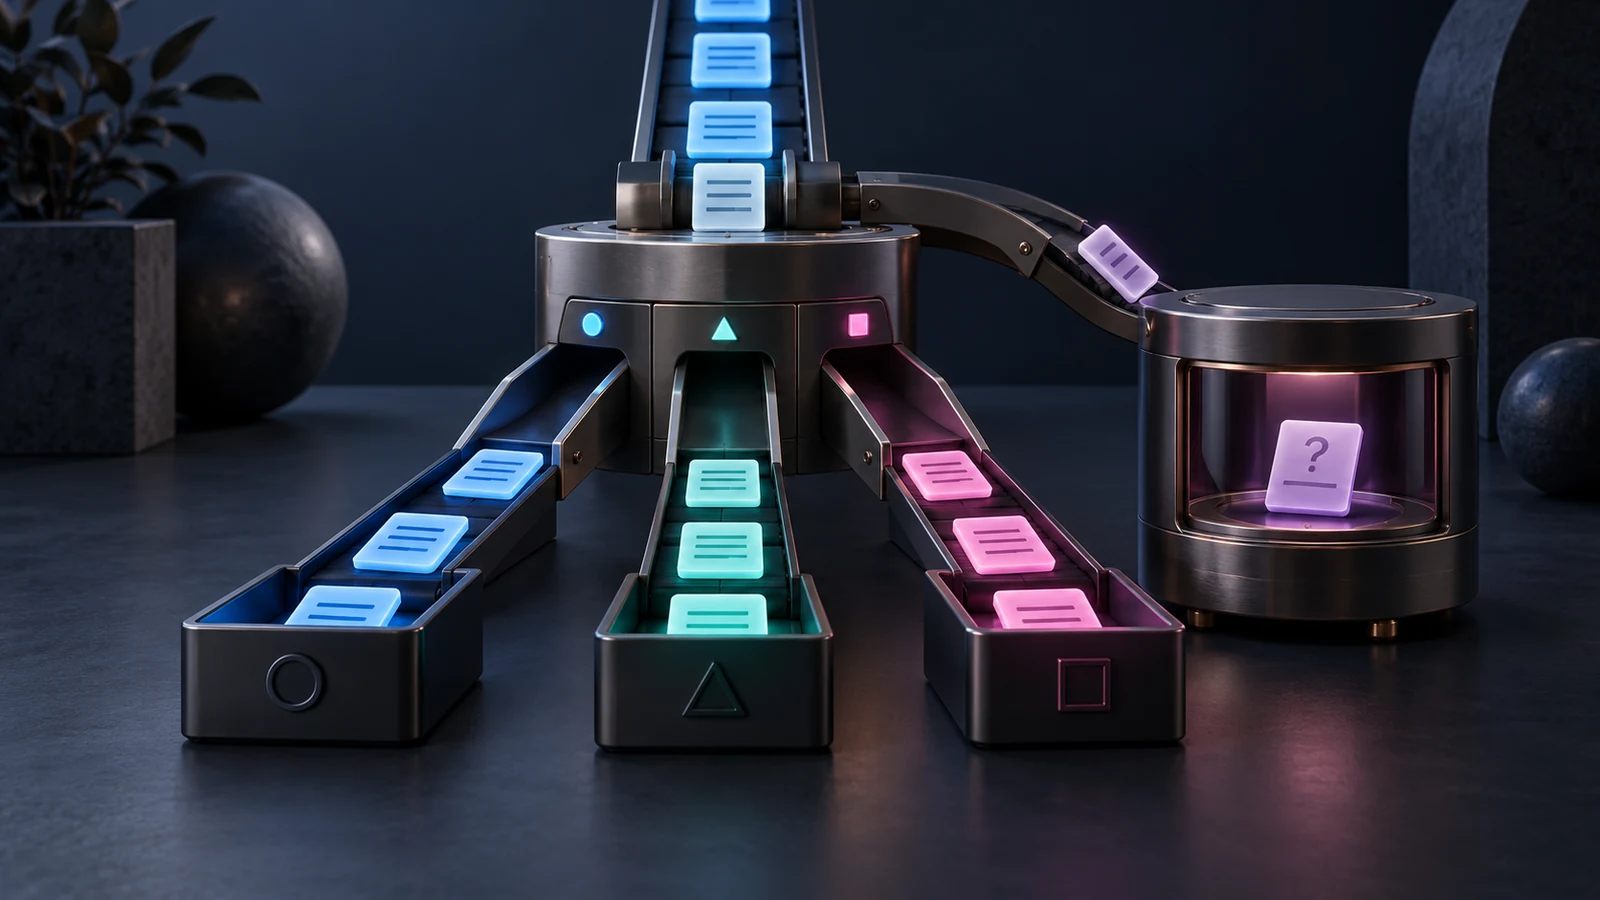
That changed in the last three weeks. A new kind of model arrived that does nothing but choose. You give it the options, it picks one, and it tells you how confident it is. Four of them landed between mid September and last Thursday, from a startup, OpenAI, Cloudflare and AWS. This post covers what they are, where they fit in the automations we build for clients, and what we are not assuming yet.
What Shipped
- Jev, from TypeSafe AI (mid September). TypeSafe was founded by Diogo Almeida, a former OpenAI researcher who worked on ChatGPT. Jev is a transformer but not a chat model. It returns calibrated probabilities over answers you define in advance, so it cannot wander off into an answer you did not offer. It is named after the economist William Stanley Jevons, output tokens are free, and input is priced by the billion tokens. Demand briefly took its API offline.
- OpenAI's Decisions API (29 September). Sam Altman previewed it in an aside at DevDay. It gives the Luna model a fixed set of options and returns probabilities, and Altman said narrowing the job to a choice makes it extremely fast while keeping image understanding and broad language support. It is a limited preview.
- Cloudflare's Clef and Clef-flash (1 October). Two open models under the Apache 2.0 licence, with 27 and 9 billion parameters, running on Workers AI. You send a state and a set of typed questions, which can be yes or no, multiple choice or a score, and you get typed answers with probabilities back. They read images as well as text and are compatible with Jev's API. In Cloudflare's own table, Clef-flash answers in a median of 38.8 milliseconds against 524 for Jev.
- AWS's Strands Decider 2B (1 October). Strands Labs, an AWS team, open-sourced a 2 billion parameter decider that runs on a laptop, taking about 153 milliseconds on an M3 MacBook for small tasks. It plugs into the Strands Agents framework as a check before every tool call, returning Proceed, Deny, Confirm or Guide. Marc Brooker, one of its authors, told TechCrunch it is the "perfect decider for a workflow step".
TypeSafe calls Jev a System One model, borrowing Daniel Kahneman's name for fast, intuitive thinking. Frontier models are System Two: slow, deliberate and expensive. The pitch is that most steps in a workflow only need the first kind.
Why a Choice Beats a Prompt
Here is how an inbound email usually gets classified today. A capable model receives the email and an instruction along the lines of "reply with one word: billing, technical or sales". It works most of the time. It also takes the better part of a second, pays for a model that could write a novel in order to produce one word, and now and then replies "Billing." with a full stop, or "This looks like a billing question", which the code then has to clean up.
A decision model removes all three problems. The options are part of the request, so the answer is always one of them. It is fast because it points at an option instead of generating text. And it returns a probability, which turns out to be the most useful part.
The probability is what lets a workflow know when it is out of its depth. If the decider says billing at 0.94, route it. If it says billing at 0.41 and technical at 0.38, that email goes to a person, or to a bigger model, with both guesses attached. A language model can be asked how sure it is, but its answer is another piece of generated text. A calibrated probability is a number you can set a threshold on and test.
Where It Fits in an Automation We Build
Take a typical AI Automation engagement: a support inbox for a business that receives a few hundred emails a day. Broken into steps, the workflow looks like this:
- Is this a real customer email? Spam, sales pitch or support. A decision.
- Which team, and how urgent? A choice and a score. A decision.
- Does the knowledge base already answer it? A decision, after a search.
- Draft the reply. Generation. This needs a language model.
- Should the agent send it, or issue the refund it is proposing? A decision, and the one that matters most.
Four of the five steps are choices, yet in most automations built this year all five run on a frontier model. With a decider on steps 1, 2, 3 and 5, the language model only runs where it is writing something, and every choice comes with a confidence that decides whether a human looks at it.
The effect on a client's bill and response times depends on their volumes, so we will measure it rather than promise it. One data point from TechCrunch's reporting: a Vercel engineer said replacing a GPT-5.6 Luna step with Jev made it 5 to 18 times faster, and more accurate.
The Guardrail That Was Too Expensive
Step 5 deserves its own section. In late September we wrote about the OpenAI agent that got around the blocks on a Services Australia portal, and the permission map we now write into every Flight Plan. The weak point in most guardrails is cost. Checking every action an agent takes with a second frontier model roughly doubles the bill, so teams check some actions, or none.
Decision models change that sum. TechCrunch cited a demo in which monitoring an agent's actions with Jev cost $2.94 per task, against $372 with a frontier model doing the watching. Strands Decider is built for exactly this job. It sits in front of each tool call and answers proceed, deny, confirm with a human, or guide the agent back on course. That is a check we can afford to run on every action, not a sample.
Which One for Which Client
- Clients on Cloudflare Workers, which covers most of the websites and lightweight APIs we build: Clef on Workers AI, next to the code that calls it, with AI Gateway capturing each decision so it can be reviewed and later used for fine-tuning.
- Clients on AWS with data that should stay in Australia: Strands Decider. It is open source and small enough to run on infrastructure the client controls, in Sydney, instead of calling a hosted API overseas. On AWS that means a container or a small GPU instance, and we will test latency there before quoting a number.
- Teams already committed to OpenAI: the Decisions API, once it is out of limited preview.
- Jev remains the reference the others benchmark against, and a sensible choice when a hosted API suits the client.
What We Are Not Assuming Yet
Calibration on your data. A probability is only useful if 0.9 really means right nine times in ten. Every vendor says its model is well calibrated on its own benchmarks. We will check that against a client's real emails, documents or tickets before any threshold goes live.
Vendor benchmarks. The numbers comparing Clef with Jev come from Cloudflare. They may well hold up. We will see.
Pricing and previews. OpenAI's API is a limited preview, and Cloudflare's announcement did not include prices. We quote nothing until there is a price list.
The options are on you. A decider cannot invent an answer, which also means it cannot tell you that your options are wrong. If a customer writes about something none of the categories cover, it will still pick one. Every question we design gets an "unsure" or "none of these" option and a threshold, and the cases that land there tell us which option is missing.
Writing is still a job for a language model. Strands' own post is clear that its decider is far worse than a reasoning model at hard problems and cannot write code, chat or summarise. This is a component, not a replacement.
What Changes in Our Flight Plans
From this month, the architecture overview in a Flight Plan sorts every AI step into one of two kinds: decide or generate. Generate steps keep the model, fallback chain and eval set we described in July and September. Decide steps get a written question, a fixed set of options including "unsure", a confidence threshold, and an escalation path for anything below it. Those questions are specs, in the same spirit as the rest of a spec-driven build. If we cannot write the options down, the step is not ready to automate.
In Takeoff & Climb we build the eval set for each decision from the client's own examples, pick the decider that suits their stack, and set the threshold from the results. In Cruise & Maintenance we watch the cases that fall below it, because those show where the workflow, or the options, need to change.
Most automation does not need a genius at every step. It needs fast, straight answers to small questions, and the sense to ask for help when it is unsure. That is what this new class of model is for.
Want an Automation That Knows When to Ask?
At Dev Force One, every AI Automation starts with a Flight Plan that maps which steps decide and which steps write, so each one runs on the right kind of model.
What that gives you:
- Faster, cheaper workflows: decision models for the routing and checking, language models only where something needs writing
- Confidence you can act on: every automated choice carries a probability, and the uncertain ones go to a person
- Guardrails on every action: a check before each step an agent takes, cheap enough to run every time
Have a manual process you would like to automate, or an automation that costs more than it should? Book a Pre-flight call and we will map it with you.